[yaxin@ubox ~]$docker images
REPOSITORY          TAG                 IMAGE ID            CREATED             VIRTUAL SIZE
eg_sshd             latest              ed9c93747fe1        45 hours ago        329.8 MB
CentOS65            latest              e55a74a32125        2 days ago          360.6 MB
[yaxin@ubox ~]$docker rmi ed9c93747fe1
Untagged: ed9c93747fe16627be822ad3f7feeb8b4468200e5357877d3046aa83cc44c6af
[yaxin@ubox ~]$docker images
REPOSITORY          TAG                 IMAGE ID            CREATED             VIRTUAL SIZE
<none>              <none>              ed9c93747fe1        45 hours ago        329.8 MB
CentOS65            latest              e55a74a32125        2 days ago          360.6 MB
[yaxin@ubox ~]$docker rmi ed9c93747fe1
Error: image_delete: Conflict, ed9c93747fe1 wasn't deleted
2014/03/22 15:58:27 Error: failed to remove one or more images
查看docker的帮助会发现有两个与删除有关的命令rm和rmi
rm Remove one or more containers
rmi Remove one or more images
[yaxin@ubox ~]$docker ps -a
CONTAINER ID        IMAGE               COMMAND                CREATED             STATUS              PORTS                   NAMES
117843ade696        ed9c93747fe1        /bin/sh -c /usr/sbin   46 hours ago        Up 46 hours         0.0.0.0:49153->22/tcp   test_sshd
[yaxin@ubox ~]$docker rm 117843ade696
Error: container_delete: Impossible to remove a running container, please stop it first
2014/03/2216:36:44 Error: failed to remove one or more containers
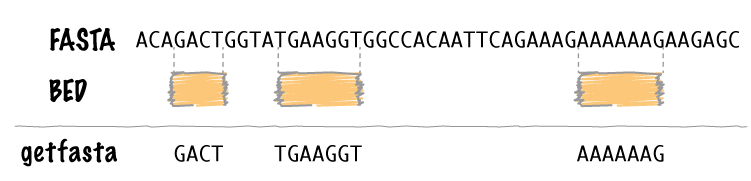
bedtoolsgetfasta extracts sequences from a FASTA file for each of the intervals defined in a BED/GFF/VCF file.
Tip
1. The headers in the input FASTA file must exactly match the chromosome column in the BED file.
2. You can use the UNIX fold command to set the line width of the FASTA output. For example, fold-w60 will make each line of the FASTA file have at most 60 nucleotides for easy viewing.
3. BED files containing a single region require a newline character at the end of the line, otherwise a blank output file is produced.
Specify an output file name. By default, output goes to stdout.
-name
Use the “name” column in the BED file for the FASTA headers in the output FASTA file.
-tab
Report extract sequences in a tab-delimited format instead of in FASTA format.
-bedOut
Report extract sequences in a tab-delimited BED format instead of in FASTA format.
-s
Force strandedness. If the feature occupies the antisense strand, the sequence will be reverse complemented. Default: strand information is ignored.
-split
Given BED12 input, extract and concatenate the sequences from the BED “blocks” (e.g., exons)
Default behavior
bedtoolsgetfasta will extract the sequence defined by the coordinates in a BED interval and create a new FASTA entry in the output file for each extracted sequence. By default, the FASTA header for each extracted sequence will be formatted as follows: “<chrom>:<start>-<end>”.
One can optionally request that FASTA records be extracting and concatenating each block in a BED12 record. For example, consider a BED12 record describing a transcript. By default, getfasta will extract the sequence representing the entire transcript (intons, exons, UTRs). Using the -split option, getfasta will instead produce separate a FASTA record representing a transcript that splices together each BED12 block (e.g., exons and UTRs in the case of genes described with BED12).
If you perform linear regression analysis, you might need to compare different regression lines to see if their constants and slope coefficients are different. Imagine there is an established relationship between X and Y. Now, suppose you want to determine whether that relationship has changed. Perhaps there is a new context, process, or some other qualitative change, and you want to determine whether that affects the relationship between X and Y.
For example, you might want to assess whether the relationship between the height and weight of football players is significantly different than the same relationship in the general population.
You can graph the regression lines to visually compare the slope coefficients and constants. However, you should also statistically test the differences. Hypothesis testing helps separate the true differences from the random differences caused by sampling error so you can have more confidence in your findings.
In this blog post, I’ll show you how to compare a relationship between different regression models and determine whether the differences are statistically significant. Fortunately, these tests are easy to do using Minitab statistical software.
In the example I’ll use throughout this post, there is an input variable and an output variable for a hypothetical process. We want to compare the relationship between these two variables under two different conditions. Here is the Minitab project file with the data.
Comparing Constants in Regression Analysis
When the constants (or y intercepts) in two different regression equations are different, this indicates that the two regression lines are shifted up or down on the Y axis. In the scatterplot below, you can see that the Output from Condition B is consistently higher than Condition A for any given Input value. We want to determine whether this vertical shift is statistically significant.
To test the difference between the constants, we just need to include a categorical variable that identifies the qualitative attribute of interest in the model. For our example, I have created a variable for the condition (A or B) associated with each observation.
To fit the model in Minitab, I’ll use: Stat > Regression > Regression > Fit Regression Model. I’ll include Output as the response variable, Input as the continuous predictor, and Condition as the categorical predictor.
In the regression analysis output, we’ll first check the coefficients table.
This table shows us that the relationship between Input and Output is statistically significant because the p-value for Input is 0.000.
The coefficient for Condition is 10 and its p-value is significant (0.000). The coefficient tells us that the vertical distance between the two regression lines in the scatterplot is 10 units of Output. The p-value tells us that this difference is statistically significant—you can reject the null hypothesis that the distance between the two constants is zero. You can also see the difference between the two constants in the regression equation table below.
Comparing Coefficients in Regression Analysis
When two slope coefficients are different, a one-unit change in a predictor is associated with different mean changes in the response. In the scatterplot below, it appears that a one-unit increase in Input is associated with a greater increase in Output in Condition B than in Condition A. We can see that the slopes look different, but we want to be sure this difference is statistically significant.
How do you statistically test the difference between regression coefficients? It sounds like it might be complicated, but it is actually very simple. We can even use the same Condition variable that we did for testing the constants.
We need to determine whether the coefficient for Input depends on the Condition. In statistics, when we say that the effect of one variable depends on another variable, that’s an interaction effect. All we need to do is include the interaction term for Input*Condition!
In Minitab, you can specify interaction terms by clicking the Model button in the main regression dialog box. After I fit the regression model with the interaction term, we obtain the following coefficients table:
The table shows us that the interaction term (Input*Condition) is statistically significant (p = 0.000). Consequently, we reject the null hypothesis and conclude that the difference between the two coefficients for Input (below, 1.5359 and 2.0050) does not equal zero. We also see that the main effect of Condition is not significant (p = 0.093), which indicates that difference between the two constants is not statistically significant.
It is easy to compare and test the differences between the constants and coefficients in regression models by including a categorical variable. These tests are useful when you can see differences between regression models and you want to defend your conclusions with p-values.




Recent Comments