|
|
In statistics, data binning is a way to categorize a number of continuous values into a smaller number of buckets (bins). Each bucket defines an numerical interval. For example, if there is a variable about house-based education levels which are measured by continuous values ranged between 0 and 19, data binning will place each value into one bucket if the value falls into the interval that the bucket covers. This post shows data binning in R as well as visualizing the bins.
The dataset contains 32038 observations for mean education level per house. Load the data into R.
data <- read.csv("data/meaneducation.csv")
x <- data[,1] #take 1st column of data frame to a vector
After loading the data, inspect the data by running
   Min. 1st Qu.  Median    Mean 3rd Qu.    Max.
   0.00   11.88   12.43   12.52   13.10   19.00
The summary data shows the range of the variable, [0,19][0,19]. The median education level per house is 12.4312.43
As the attribute is continuous, the data distribution can be visualized in a probability distribution graph. The following script creates a density plot showing the probability distribution of x.
library(ggplot2)
ggplot(data=data, aes(x=data[,1])) +
  geom_density(fill='lightblue') +
  geom_rug() +
  labs(x='mean education per house')

While the density plot is informative, it might be too technical for less technical people to read. In this case, the better data visualization is binning the data into discrete categories and plotting the count of each bin. A sample script is provided below for creating bins and plot bin counts in a bar chart.
Creating bins
# set up boundaries for intervals/bins
breaks <- c(0,2,5,8,10,13,15,19,21)
# specify interval/bin labels
labels <- c("<2", "2-5)", "5-8)", "8-10)", "10-13)", "13-15)", "15-19)", ">=19")
# bucketing data points into bins
bins <- cut(x, breaks, include.lowest = T, right=FALSE, labels=labels)
# inspect bins
summary(bins)
    <2   2-5)   5-8)  8-10) 10-13) 13-15) 15-19)    19-
   120      0     24    330  22595   7760   1200      9
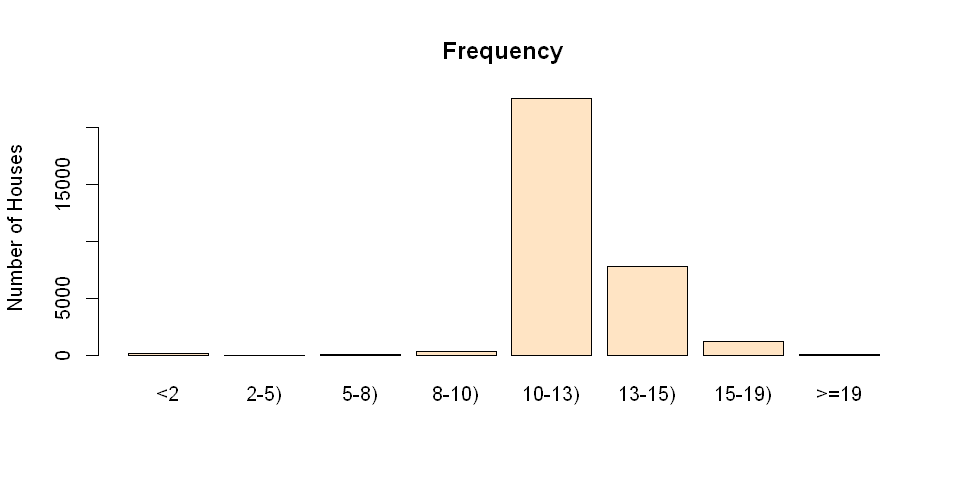
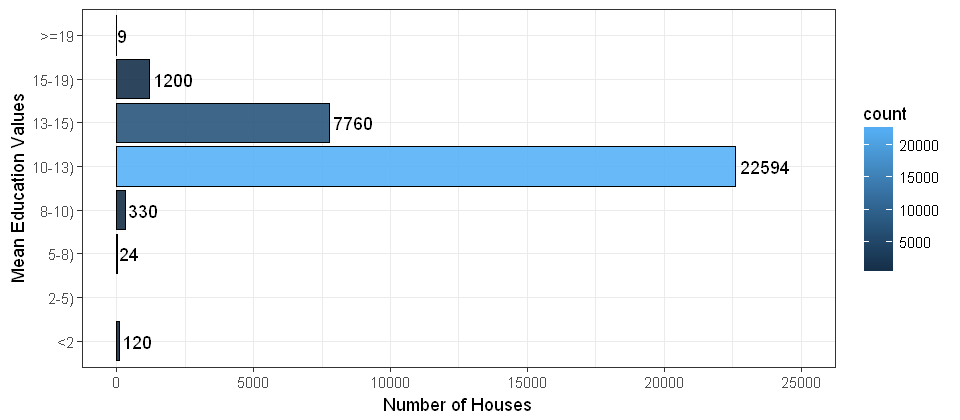
The script above results in a factor bins with 8 levels. Each level is marked by a string in the vector labels. Each value in bins indicates the level that the observation falls into. The summary of bins lists the count for each bin.
Plotting the bins
After generating the bins, simply plot the bins by the following script:
plot(bins, main="Frequency", ylab="Number of Houses",col="bisque")
Using ggplot
y <- cbind(data, bins)
ggplot(data=y, aes(x=y$bins,fill=..count..)) +
  geom_bar(color='black', alpha=0.9) +
  stat_count(geom="text", aes(label=..count..), hjust=-0.1) +
  theme_bw() +
  labs(y="Number of Houses",x="Mean Education Values") +
  coord_flip() +
  ylim(0,25000) +
  scale_x_discrete(drop=FALSE) # include the bins of length zero
Histograms and Density Plots
Histograms
You can create histograms with the function hist(x) where x is a numeric vector of values to be plotted. The option freq=FALSE plots probability densities instead of frequencies. The option breaks= controls the number of bins.
# Simple Histogram

hist(mtcars$mpg)
 click to view
# Colored Histogram with Different Number of Bins

hist(mtcars$mpg, breaks=12, col="red")
 click to view
# Add a Normal Curve (Thanks to Peter Dalgaard)

x <- mtcars$mpg

h<-hist(x, breaks=10, col="red", xlab="Miles Per Gallon",

main="Histogram with Normal Curve")

xfit<-seq(min(x),max(x),length=40)

yfit<-dnorm(xfit,mean=mean(x),sd=sd(x))

yfit <- yfit*diff(h$mids[1:2])*length(x)

lines(xfit, yfit, col="blue", lwd=2)
 click to view
Histograms can be a poor method for determining the shape of a distribution because it is so strongly affected by the number of bins used.
To practice making a density plot with the hist() function, try this exercise.
Kernel Density Plots
Kernal density plots are usually a much more effective way to view the distribution of a variable. Create the plot using plot(density(x)) where x is a numeric vector.
# Kernel Density Plot

d <- density(mtcars$mpg) # returns the density data

plot(d) # plots the results
 click to view
# Filled Density Plot

d <- density(mtcars$mpg)

plot(d, main="Kernel Density of Miles Per Gallon")

polygon(d, col="red", border="blue")
 click to view
Comparing Groups VIA Kernal Density
The sm.density.compare( ) function in the sm package allows you to superimpose the kernal density plots of two or more groups. The format is sm.density.compare(x, factor) where x is a numeric vector and factor is the grouping variable.
# Compare MPG distributions for cars with

# 4,6, or 8 cylinders

library(sm)

attach(mtcars)
# create value labels
cyl.f <- factor(cyl, levels= c(4,6,8),
labels = c("4 cylinder", "6 cylinder", "8 cylinder"))
# plot densities
sm.density.compare(mpg, cyl, xlab="Miles Per Gallon")
title(main="MPG Distribution by Car Cylinders")
# add legend via mouse click
colfill<-c(2:(2+length(levels(cyl.f))))
legend(locator(1), levels(cyl.f), fill=colfill)
 click to view
文章:Accurate binning of metagenomic contigs via automated clustering sequences using information of genomic signatures and marker genes 2016 (https://www.ncbi.nlm.nih.gov/pubmed/27067514)
文章:MetaCRAM: an integrated pipeline for metagenomic taxonomy identification and compression 2016
(http://www.ncbi.nlm.nih.gov/pubmed/26895947)
文章:Evaluating the Quantitative Capabilities of Metagenomic Analysis Software 2016 (http://www.ncbi.nlm.nih.gov/pubmed/26831696)
文章:MaxBin 2.0: an automated binning algorithm to recover genomes from multiple metagenomic datasets 2016 (http://www.ncbi.nlm.nih.gov/pubmed/26515820)
文章:Metagenomic Classification Using an Abstraction Augmented Markov Model 2015
(http://www.ncbi.nlm.nih.gov/pubmed/26618474)
文章:DectICO: an alignment-free supervised metagenomic classification method based on feature extraction and dynamic selection 2015 (http://www.ncbi.nlm.nih.gov/pubmed/26446672)
文章:MetaPhlAn2 for enhanced metagenomic taxonomic profiling 2015 (http://www.ncbi.nlm.nih.gov/pubmed/26418763)
文章:Multi-Layer and Recursive Neural Networks for Metagenomic Classification 2015 (http://www.ncbi.nlm.nih.gov/pubmed/26316190)
文章:deFUME: Dynamic exploration of functional metagenomic sequencing data 2015 (http://www.ncbi.nlm.nih.gov/pubmed/26227142)
文章:Spaced seeds improve k-mer-based metagenomic classification 2015 (http://www.ncbi.nlm.nih.gov/pubmed/26209798)
文章:Investigating microbial co-occurrence patterns based on metagenomic compositional data 2015 (http://www.ncbi.nlm.nih.gov/pubmed/26079350)
文章:Reconstructing 16S rRNA genes in metagenomic data 2015 (http://www.ncbi.nlm.nih.gov/pubmed/26072503)
文章:Bayesian mixture analysis for metagenomic community profiling 2015 (http://www.ncbi.nlm.nih.gov/pubmed/26002885)
文章:MICCA: a complete and accurate software for taxonomic profiling of metagenomic data 2015
(http://www.ncbi.nlm.nih.gov/pubmed/25988396)
文章:Identifying personal microbiomes using metagenomic codes 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25964341)
文章:CS-SCORE: Rapid identification and removal of human genome contaminants from metagenomic datasets 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25944184)
文章:TreeSeq, a Fast and Intuitive Tool for Analysis of Whole Genome and Metagenomic Sequence Data 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25933115)
文章:MUSiCC: a marker genes based framework for metagenomic normalization and accurate profiling of gene abundances in the microbiome 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25885687)
文章:CLARK: fast and accurate classification of metagenomic and genomic sequences using discriminative k-mers 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25879410)
文章:Woods: A fast and accurate functional annotator and classifier of genomic and metagenomic sequences 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25863333)
文章:METAXA2: improved identification and taxonomic classification of small and large subunit rRNA in metagenomicdata 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25732605)
文章:Exploiting topic modeling to boost metagenomic reads binning 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25859745)
文章:MBBC: an efficient approach for metagenomic binning based on clustering 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25652152)
文章:VizBin – an application for reference-independent visualization and human-augmented binning of metagenomicdata 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25621171)
文章:Binpairs: utilization of Illumina paired-end information for improving efficiency of taxonomic binning of metagenomicsequences 2015 (http://www.ncbi.nlm.nih.gov/pubmed/25551450)
文章:MetaObtainer: A Tool for Obtaining Specified Species from Metagenomic Reads of Next-generation Sequencing 2015 (https://www.ncbi.nlm.nih.gov/pubmed/26293485)
文章:MetaBoot: a machine learning framework of taxonomical biomarker discovery for different microbial communities based on metagenomic data 2015 (https://www.ncbi.nlm.nih.gov/pubmed/26213658)
文章:BioMaS: a modular pipeline for Bioinformatic analysis of Metagenomic AmpliconS 2015 (https://www.ncbi.nlm.nih.gov/pubmed/26130132)
文章:FCMM: A comparative metagenomic approach for functional characterization of multiple metagenome samples 2015 (https://www.ncbi.nlm.nih.gov/pubmed/26027543)
文章:MetaGeniE: characterizing human clinical samples using deep metagenomic sequencing 2014 (http://www.ncbi.nlm.nih.gov/pubmed/25365329)
文章:Binning metagenomic contigs by coverage and composition 2014 (https://www.ncbi.nlm.nih.gov/pubmed/25218180)
文章:COVER: a priori estimation of coverage for metagenomic sequencing 2012 (http://www.ncbi.nlm.nih.gov/pubmed/23760797
机器上总是会有Python2.7的版本和Python3.x的版本,今天接触到一台服务器上面有Python2.7和Python3.4,想在Python3.4下安装一个TensorFlow,但不管怎么装都只能装到Python2.7上,特别头疼,后来发现是因为不论用pip还是pip3,都是指向的Python2.7。
查看pip指向
按照这篇博客中说的方法,检查了一遍pip和pip3分别指向的Python:
$ pip -V
$ pip3 -V
1
2
3
发现居然都指向了Python2.7:
怪不得怎么装都是装到了Python2.7环境下。
所以我们的问题变成了怎么通过pip去指定安装到Python3.x下。
怪不得怎么装都是装到了Python2.7环境下。
所以我们的问题变成了怎么通过pip去指定安装到Python3.x下。
解决方案
更改pip3指向
一种方法是更改pip与pip3其中一个的指向,一般pip指向Python2.7,pip3指向Python3.x。这种方法可以一劳永逸地让之后的pip3安装都顺利一点,方法参考这篇博客。我并没有用这种方法,所以也没实测。
强制安装到Python3.x环境下
如果我们直接用命令“pip3 install <库名>”,那么是默认安装到pip3指向的Python环境的,但是我们也可以强制安装到Python3.x:
$ sudo python3 -m pip install tensorflow-gpu
———————
作者:Cloudox_
来源:CSDN
原文:https://blog.csdn.net/Cloudox_/article/details/78616378
版权声明:本文为博主原创文章,转载请附上博文链接!
ARGs_OAP_v2.0(步骤1):https://github.com/biofuture/Ublastx_stageone
ARGs-OAP在线分析网站(步骤2): http://smile.hku.hk/SARGs
无处不在的抗性基因
环境中抗生素抗性基因(ARGs)的来源:
随机突变或表达潜在抗性基因等方式使细菌体内基因组上存在的抗性基因原型、准抗性基因或潜在抗性基因被表达出来,从而使细菌获得的抗生素抗性。
抗生素在人和动物肠道内诱导产生耐药菌,这些编码ARGs的耐药菌经由粪便排出并进入环境中,是环境中ARGs的重要来源。
抗性基因的水平转移是抗性基因在环境中传播的的主要机制,通过将包含抗性基因的质粒、转座子、整合子作为载体,通过细菌之间细胞与细胞的接触,将抗性基因从载体细胞转移到受体细胞。
如何检测环境中抗生素抗性基因(ARGs):
- PCR技术—定性。
- qPCR技术—定量。
- 宏基因组测序:以环境样品中的整个微生物群体基因组为研究对象,检测环境样本微生物中的物种组成、丰度,基因预测、基因丰度,利用数据库进行注释,得到样本中ARGs的种类和丰度与样本的相关性。
- ARDB数据库:主要包含细菌病原菌的多种抗性基因数据,不能为环境样本宏基因组数据提供详细的ARG概况(即对每个检测到的ARG提供type/subtype的ARG分类信息和丰度信息)。
- CARD数据库:以Antibiotic Resistance Ontology(ARO)为分类单位的形式所构建,ARO用于关联抗生素模块及其目标、抗性机制、基因变异等信息。
ResFinder:需要较长的查询reads。对于在ResFinder中被检测为ARG的序列,其必须至少覆盖数据库中匹配ARG长度的五分之二,具有不小于50%的相似性。
- ARGO:侧重于万古霉素和β-内酰胺抗性基因。
ARG-ANNOT:设计用于检测细菌基因组中的ARG而不是环境样品。
构建ARG综合数据库SARG v1.0
- 整合CARD和ARDB数据库
CARD数据库2,513条序列;
ARDB数据库7,828条序列;
去除586条共享序列;
SARG包含4246条ARGs参考序列。
- 去除非ARG序列
- 去除冗余序列(完整蛋白质序列具有100%同一性)
- 去除与SNP相关的ARG序列
- 去除描述为“假定蛋白质”或“未命名蛋白质”的序列
- 构建结构化ARG数据库SARG
构建ARG综合数据库SARG v2.0
- 使用SARG v1.0作为从NCBI-NR获取潜在ARG序列的种子。
- NCBI-NR序列BLASTP比对SARG v1.0数据库(e-value:1e-7, identity: 90%、80%、70%); levels: Accurate, Moderate and Loose 。
- 基于序列相似度或关键字匹配将ARG序列分配给不同的Subtype。
- 合并时,删除有多个分类结果的序列,只保留具有匹配分类(type和subtype)的序列。
Number of ARGs reference genes in core SARG database (column ‘core SARG’) and updated SARG database using different cut off of identity (90%, 80% and 70%) for retrieving. A is the profile before using parallel classification to seat each sequence into hierarchical structure. B is the results of sequences amount after being classified into specific ARGs types and subtypes.
ARGs-OAP概述
ARGs-OAP是一个抗生素抗性基因分析平台、在线分析工具。
ARGs-OAP可以从宏基因组数据集中快速鉴定并定量分析抗生素抗性基因。
ARGs-OAP中包含一个结构化ARG数据库SARG(type–subtype–reference sequence)。
ARGs-OAP 1.0版包括CARD及ARDB数据库的序列, 2.0版新纳入了NCBI-NR数据库中的ARG序列。
使用ARGs-OAP 进行注释后,对获得的ARGs:可以通过总reads数、16S rRNA基因拷贝数和细胞数量进行ARGs丰度标准化;2.0版优化了细胞数量定量分析过程。
ARGs-OAP在线工具使用步骤
1.本地计算机预先筛选潜在的ARG序列,以减少上传序列文件的大小;
2.使用在线平台注释/分类ARG序列。
对于宏基因组数据,快速预筛选可去除总序 列> 99.3%的不相关序列,显着减少上传文件的大小并加速在线BLASTX分析。
步骤2:上传预筛选后的ARG序列数据至online pipeline。
ARGs_OAP_v2.0(步骤1):https://github.com/biofuture/Ublastx_stageone
ARGs-OAP在线分析网站(步骤2): http://smile.hku.hk/SARGs
The output files can be downloaded as tables listing the abundances of ARGs types/subtypes in different units:
“ppm” (number of ARGs sequences in one million sequences) ;
“copies of ARG per copy of 16S rRNA” ;
“copies of ARG per prokaryote’s cell” .
当数据集包含新ARG时(即数据集2):identity cutoff 设置为高于60%,则MCC值显著下降(图4a和4b),此水平下灵敏度也显著降低(图3d和4e),数据库的不完整性对注释精度影响不大(图4g和4h)。
E-value 对这三个评估指标的影响:MCC值和精度随着E-value的减小而增加,但灵敏度没有太大变化。
评估序列长度的影响:较长的读长导致较高的MCC和灵敏度(图3b和3c )。
最佳E-value 和 identity cutoff 值:与E值相比, identity值显示出更大的影响。蓝色箭头表示在以前ARGs注释( E-value为1e-5, identity为90%)中对短读数宏基因组数据进行分析时,MCC值和灵敏度较低假阴性率很高,并且错过了许多ARG样序列。为了揭示更全面的ARG概况,基于使用模拟数据集2所示的MCC结果,如红色箭头所示,建议的最佳identity cutoff 为60%,E-value为1e-7。
序列覆盖度小于85%时,灵敏度和MCC值几乎没有影响。
序列覆盖度从85%增加到100%时,灵敏度和MCC值急剧下降。
更严格的序列覆盖度会错过更多类似ARG的序列。
参考文献:
Yang Y, Jiang X, Chai B, et al. ARGs-OAP: online analysis pipeline for antibiotic resistance genes detection from metagenomic data using an integrated structured ARG-database[J]. Bioinformatics, 2016, 32(15):2346.
Yin X, Jiang X T, Chai B, et al. ARGs-OAP v2.0 with an Expanded SARG Database and Hidden Markov Models for Enhancement Characterization and Quantification of Antibiotic Resistance Genes in Environmental Metagenomes[J]. Bioinformatics, 2018
作者:周运来就是我
链接:https://www.jianshu.com/p/feb181e7888e
來源:简书
简书著作权归作者所有,任何形式的转载都请联系作者获得授权并注明出处。
发音第一个 n 带鼻音
analysis (noun single )
analyses (noun) (multiplex number of analysis)
动词
analyse a’ n(ə)lʌɪz 发音a 不带鼻音
th 在尾巴 发 f
thanks
中间ch发k的时候要弱化发音
1199 git clone https://github.com/GPZ-Bioinfo/tmap.git
1200 cd tmap
1201 ll
1202 python setup.py install
1203 ll
1204 cd ../
1205 rm -rf tmap
1206 deactivate
1207 rmvirtualenv tmap_ENV
1208 mkvirtualenv -p /usr/bin/python3.4m tmap_ENV
pip3 install pypiwin32
conda install scipy
sudo pip3 install matplotlib
Install
The installation of file manager is very simple.
- install latest version of node.js.
- install
cloudcmd via npm with:
When in trouble use:
npm i cloudcmd -g --force
sudo vi /usr/lib/node_modules/cloudcmd/json/config.json
“dirStorage”: false,
“online”: true,
“open”: false,
“keysPanel”: true,
“port”: 8080,
“ip”: “143.89.31.17”,
“root”: “/”,
“prefix”: “”,
“progress”: true,
“contact”: true,
“confirmCopy”: true,
“confirmMove”: true,
“configDialog”: true,
“oneFilePanel”: false,
“console”: true,
“syncConsolePath”: false,
“terminal”: false,
“terminalPath”: “”,
“showConfig”: false,
“showFileName”: false,
“vim”: false,
“columns”: “name-size-date-owner-mode”,
“export”: false,
“exportToken”: “root”,
“import”:false,
“importToken”: “root”,
“importUrl”: “http://143.89.31.17:8080″,
“importListen”: false,
“log”: true
open 8080 port to let access 143.89.31.17:8080
993 systemctl start firewalld
994 systemctl status firewalld
995 firewall-cmd –permanent –add-port=8080/tcp
996 sudo firewall-cmd –permanent –add-port=8080/tcp
997 firewall-cmd –reload
998 sudo firewall-cmd –reload
999 sudo vi /usr/lib/node_modules/cloudcmd/json/config.json
import sklearn
import plotly.plotly as py
import plotly.graph_objs as go

import matplotlib.pyplot as plt
import numpy as np

from sklearn.cluster import DBSCAN
from sklearn import metrics
from sklearn.datasets.samples_generator import make_blobs
from sklearn.preprocessing import StandardScaler


###################################
# Load libraries
from sklearn import datasets
from sklearn.preprocessing import StandardScaler
from sklearn.cluster import DBSCAN
from sklearn.preprocessing import MinMaxScaler

###################################


shenzy@SZYENVS:~/software/tmap$ python
Python 2.7.13 |Continuum Analytics, Inc.| (default, Dec 20 2016, 23:09:15)
[GCC 4.4.7 20120313 (Red Hat 4.4.7-1)] on linux2
Type "help", "copyright", "credits" or "license" for more information.
Anaconda is brought to you by Continuum Analytics.
Please check out: http://continuum.io/thanks and https://anaconda.org
>>> from sklearn import datasets
>>> import pandas as pd
>>> import sklearn
>>> from sklearn import datasets
>>> from sklearn.preprocessing import StandardScaler
>>> from sklearn.cluster import DBSCAN
>>> from sklearn.preprocessing import MinMaxScaler
>>> iris = datasets.load_iris()
>>> X = iris.data
>>> X = pd.DataFrame(X,columns = iris.feature_names)
>>> from tmap.tda import mapper, filter
>>> from tmap.tda.cover import Cover
>>> # Step1. initiate a Mapper
... tm = mapper.Mapper(verbose=1)
>>>
>>> # Step2. Projection
... lens = [filter.MDS(components=[0, 1])]
>>> projected_X = tm.filter(X, lens=lens)
Filtering by MDS.
...calculate distance matrix using the euclidean metric.
Finish filtering of points cloud data.
>>> clusterer = DBSCAN(eps=0.75, min_samples=1)
>>> cover = Cover(projected_data=MinMaxScaler().fit_transform(projected_X), resolution=20, overlap=0.75)
>>> graph = tm.map(data=StandardScaler().fit_transform(X), cover=cover, clusterer=clusterer)
Mapping on data (150, 4) using lens (150, 2)
...minimal number of points in hypercube to do clustering: 1
...create 296 nodes.
...calculate projection coordinates of nodes.
...construct a TDA graph.
...create 1394 edges.
Finish TDA mapping
>>> print(len(graph['nodes']),len(graph['edges']))
(296, 1394)
>>> print(graph['nodes'].items())
cat file_with_ids.txt | while read p; do echo $p; esearch -db nucleotide -query $p | efetch -format fasta > $p.fasta; done;
cat ginumber.txt| while read p; do echo $p; efetch -db nucleotide -id $p -format gb > $p.gbk; done;
shenzy@SZYENVS:~/work/zhongshan/virus_database$ cat ginumber.txt| while read p; do echo $p; efetch -db nucleotide -id $p -format gb > $p.gbk; done;
AY180661
AY180662
AY180663
AY180664
AY180665
AY180666
AY180667
AY180668
AY180669
AY180670
AY180671
AY180672
AY180673
AY180674
AY180675
AY180676
AY180677
|
|


Recent Comments